TwoBufQueue
生产者小缓存,批量复制,独立处理回调。
让生产者保持小缓存,让消费者拥有处理积压的空间。
连续发送一批消息,对业务性能产生什么影响
正常执行业务 → 连续发送一批消息 → 立刻执行业务 · 2–16 MiB
打开报告 →WriteSession单块循环写入
256 MiB · 回调循环为 0 · 三轮独立运行
打开报告 →块交接时发布普通 write:最大发布批次
256 MiB · 回调循环为 0 · 三轮独立运行
打开报告 →每条消息发布普通 write:每条发布
256 MiB · 回调循环为 0 · 三轮独立运行
打开报告 →连续发送后的业务性能
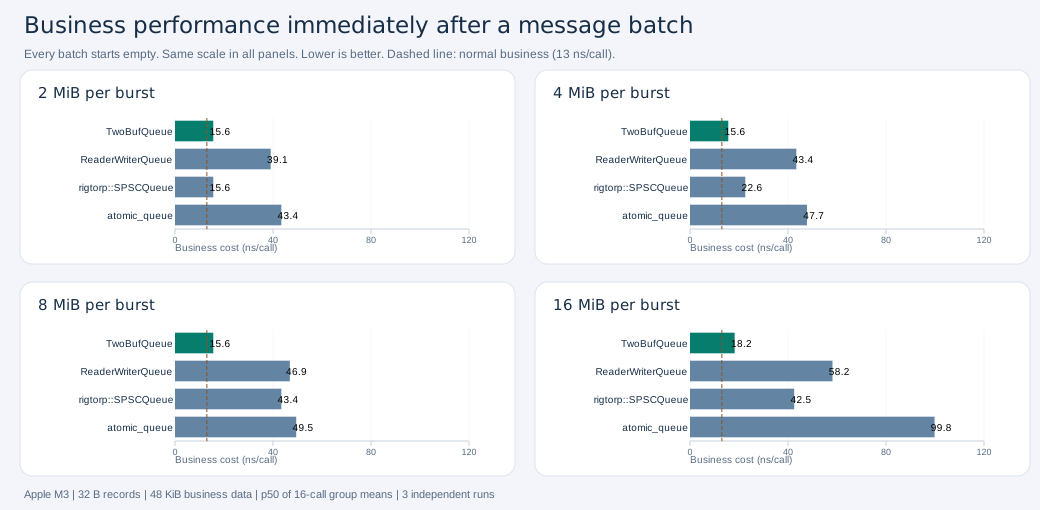
正常执行业务 → 连续发送一批消息 → 立刻执行相同业务。每批从零积压开始,消费者持续运行,排空不计时。所有队列使用相同的 48 KiB 业务数据、32 B 消息和 64 次回调循环。TwoBufQueue 使用 16 KiB 第一层缓存与 256 MiB 第二层缓存,开源 SPSC 使用 256 MiB 槽位存储。
正常业务约为 13 ns/次(虚线)。发送 16 MiB 后,TwoBufQueue 为 18.2 ns/次(1.40 倍),ReaderWriterQueue 为 58.2 ns,rigtorp 为 42.5 ns,atomic_queue 为 99.8 ns。发送 2 MiB 后,TwoBufQueue 与 rigtorp 均为 15.6 ns/次。
每组 16 次业务调用平均耗时的 p50,再取三轮平均。生产者采用高 QoS,未硬绑核。 完整结果、比值与初始化参数.指标怎么看
写入报告按每组 1,000 次发送统计生产者提交耗时;业务报告按每组 16 次调用统计业务执行耗时。它们不是单条消息或端到端延时。各报告公开线程数、两层缓存和对照负载的复制方式,结果适用于记录的测试配置。
其他测量与历史实验
- performance 256m callback
- performance 256m callback session
- performance 8m 16b 32b 64b tuned
- performance 8m 16b 32b tuned
- performance 8m 32b latency
- performance 8m zero
- performance 8m zero session
- performance burst business sizes
- performance burst tail 1m
- performance burst tail instruction 1m
- performance hot path cache
- performance optimal ordinary readback reader2g zero
- performance optimal three modes reader2g zero
- test per write block size only writer publish1
- test per write block size only writer publish max
- test per write block size only writer reader80 3runs publish1
- test per write block size only writer reader80 3runs publish max
- test per write block size readback fixed reader 3runs
- test per writer block size
- test per writer block size cache hits
- test per writer block size max comparison 3runs
- test per writer block size no current
- test per writer block size no current publish1
- test per writer block size reader80 3runs max